Joint local objective
The client learns from known labels and retained pseudo-labels in one update. β = 0.5 weights the unlabeled term in the reported experiments.
ACM TECS §4.1–4.3, Eqs. 3 and 7. Both losses are computed before backpropagation.
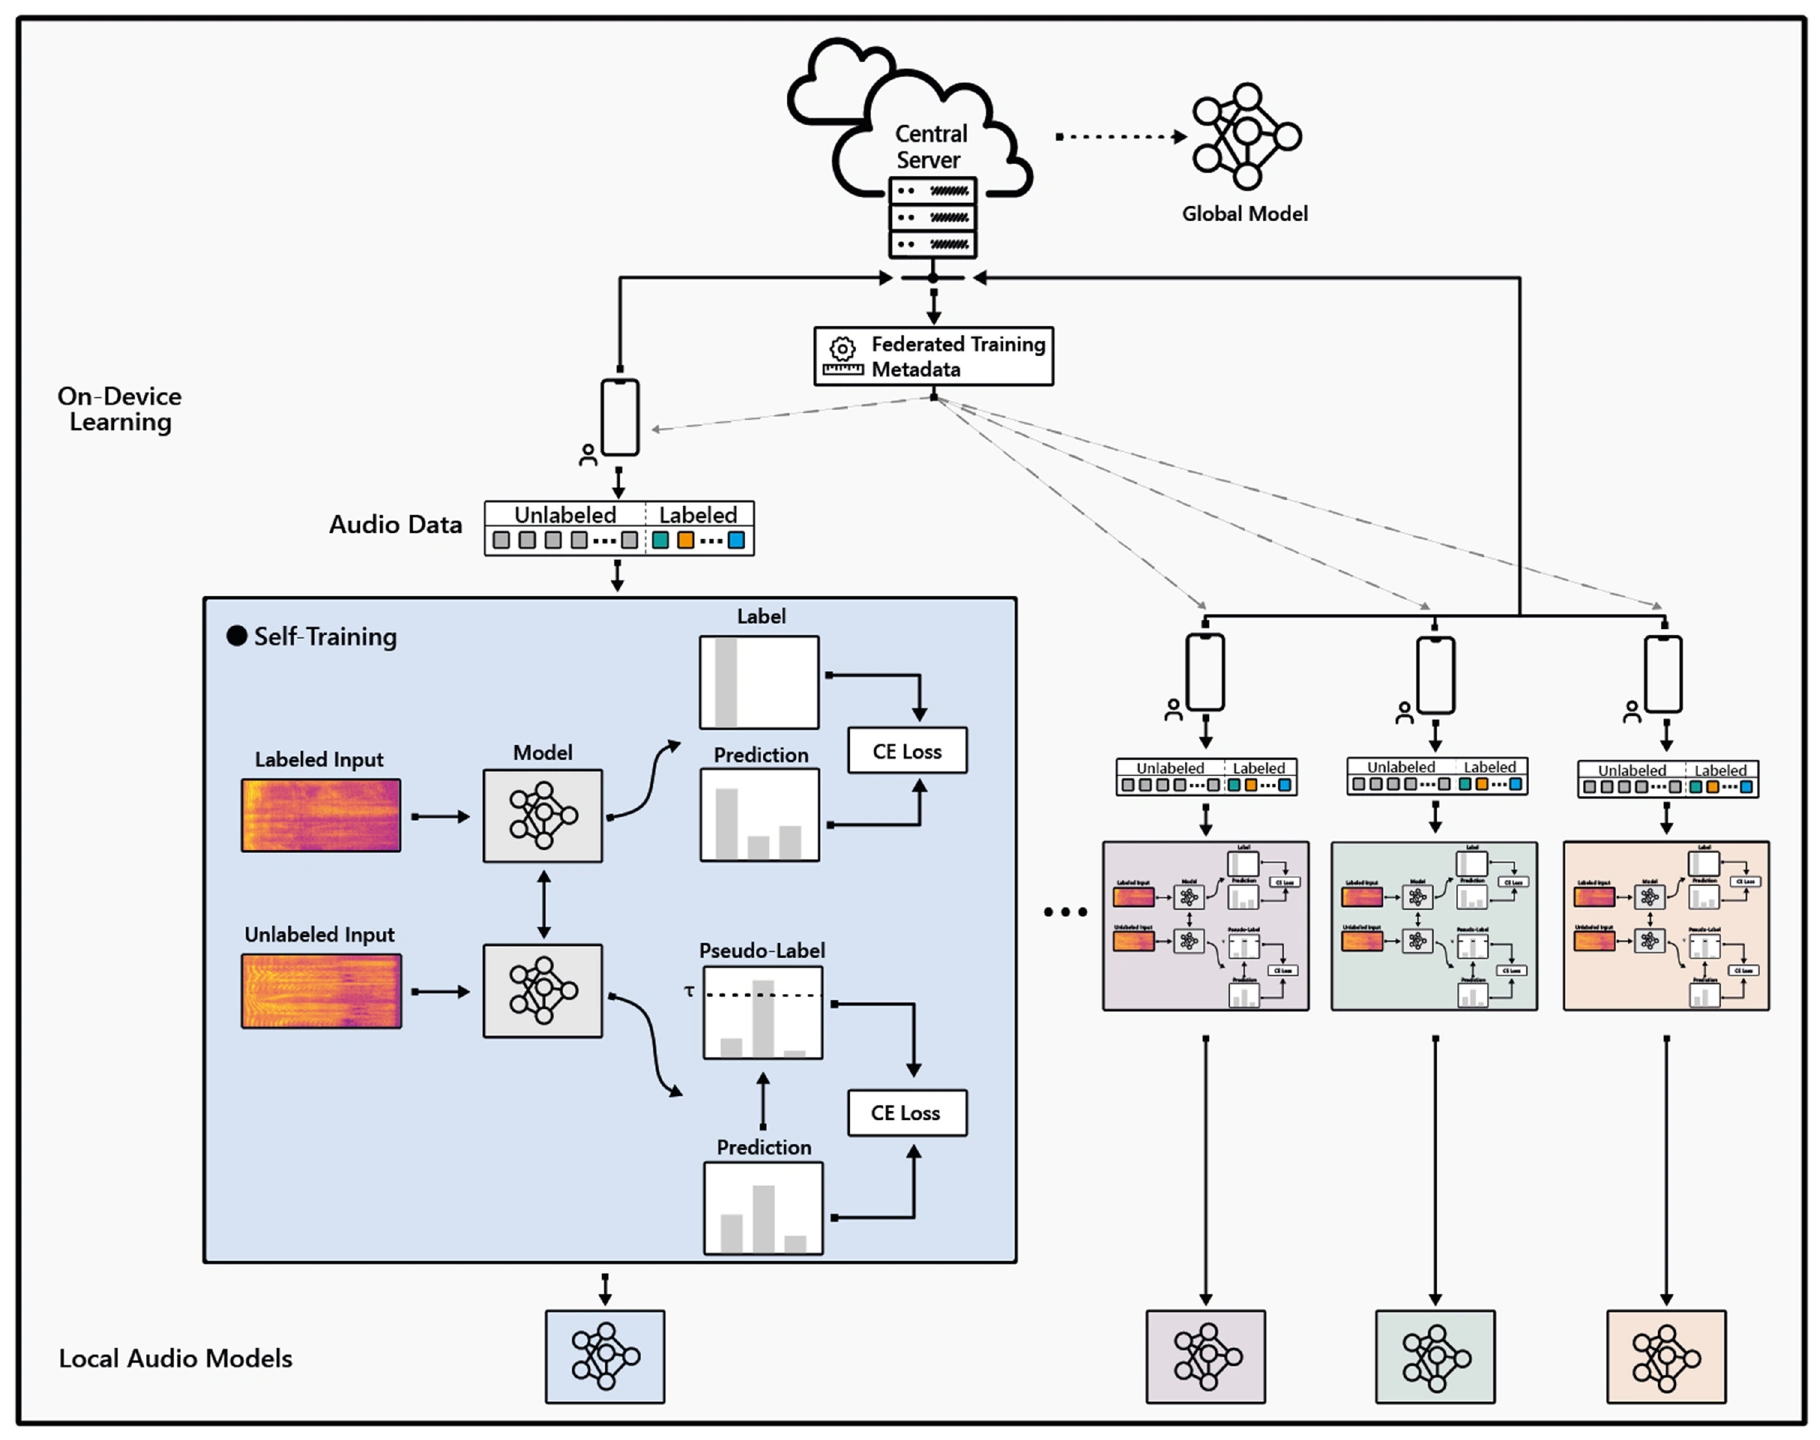
Turn unlabeled audio into shared learning
Most device audio has no labels. FedSTAR turns selected local predictions into training targets, combining them with known labels before sharing model updates. Optional public-audio pretraining supplies a stronger starting point.
Local self-training brings unlabeled audio into the same update as labeled examples.
Temperature and confidence filtering limit which predicted targets influence learning.
Optional contrastive initialization improves early convergence; three audio tasks test label scarcity and client variation.
Federated Learning is a distributed machine learning paradigm dealing with decentralized and personal datasets. Since data reside on devices such as smartphones and virtual assistants, labeling is entrusted to the clients or labels are extracted in an automated way. Specifically, in the case of audio data, acquiring semantic annotations can be prohibitively expensive and time-consuming. As a result, an abundance of audio data remains unlabeled and unexploited on users’ devices. Most existing federated learning approaches focus on supervised learning without harnessing the unlabeled data. In this work, we study the problem of semi-supervised learning of audio models via self-training in conjunction with federated learning. We propose FedSTAR to exploit large-scale on-device unlabeled data to improve the generalization of audio recognition models. We further demonstrate that self-supervised pre-trained models can accelerate the training of on-device models, significantly improving convergence within fewer training rounds. We conduct experiments on diverse public audio classification datasets and investigate the performance of our models under varying percentages of labeled and unlabeled data. Notably, we show that with as little as 3% labeled data available, FedSTAR on average can improve the recognition rate by 13.28% compared to the fully supervised federated model.
Read more ↗The client learns from known labels and retained pseudo-labels in one update. β = 0.5 weights the unlabeled term in the reported experiments.
ACM TECS §4.1–4.3, Eqs. 3 and 7. Both losses are computed before backpropagation.
Apply softmax to temperature-scaled logits, take the most likely class and retain predictions above τ. Temperature is 4; the cosine threshold increases from 0.5 to 0.9.
Eq. 5 and Table 2. Confidence filtering reduces exposure to uncertain targets; it does not guarantee correct labels.
A sampled set of clients trains locally and returns model parameters. FedAvg forms a data-weighted average; the self-training change is inside the client update.
Algorithm 1, PDF p. 12. Experiments simulate clients with the Flower framework.
Contrastive pretraining on FSD-50K supplies initial encoder weights. The projection layer is discarded before downstream learning.
§4.4 and Figure 6. Better performance after 10 rounds is distinct from final accuracy after 100 rounds.
15 clients · 100 rounds · accuracy (%)
Speech Commands · 50% unlabeled pool · 100 rounds
| Labels | Random (%) | Pretrained (%) |
|---|---|---|
| 3% | 85.40 ± 0.008 | 85.17 ± 0.001 |
| 5% | 88.52 ± 0.005 | 88.28 ± 0.002 |
| 20% | 92.24 ± 0.012 | 93.67 ± 0.005 |
| 50% | 92.26 ± 0.005 | 93.83 ± 0.003 |
@article{tsouvalas2022fedstar,
  author = {Tsouvalas, Vasileios and Saeed, Aaqib and Ozcelebi, Tanir},
  title = {Federated Self-training for Semi-supervised Audio Recognition},
  journal = {ACM Transactions on Embedded Computing Systems},
  year = {2022},
  volume = {21},
  number = {6},
  articleno = {74},
  numpages = {26},
  doi = {10.1145/3520128},
  url = {https://doi.org/10.1145/3520128}
}