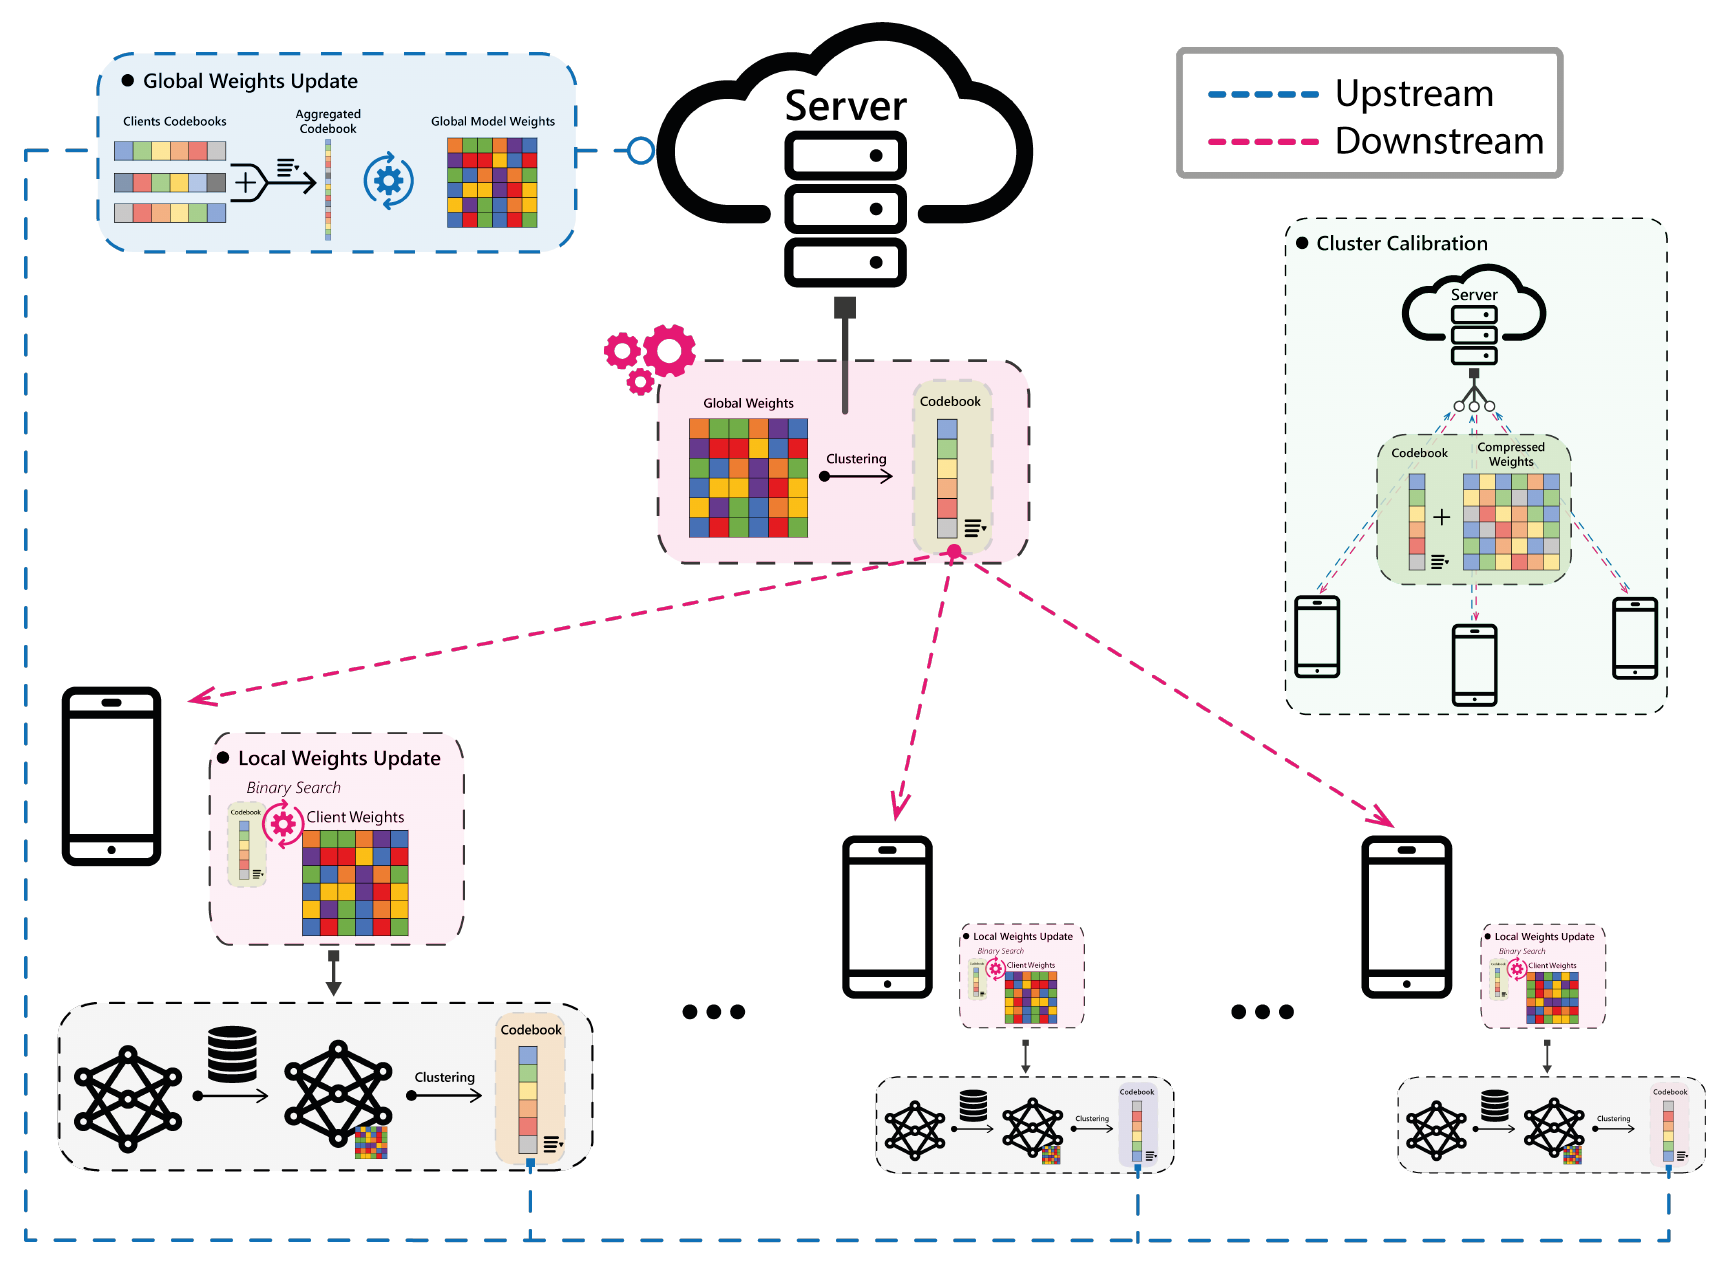
Send the shared values more often than their positions. FedCode usually exchanges only weight-cluster codebooks. Clients and server map their existing weights to received centers, while periodic transfers of weight indices recalibrate the models.
Inside FedCode
Separate values from positionsA clustered model contains a codebook of shared values and an index for every weight position. FedCode’s additional saving comes from usually omitting that large index map.Map local weights to received centersThe server sorts and broadcasts its codebook. Each client uses nearest-center binary search to replace local weight values, then trains on its own data.Update the server from client codebooksClients cluster their trained models and return the centers. The server concatenates those codebooks and replaces global weight values by nearby received centers before preparing the next codebook.Recalibrate weight positions periodicallyClusters and assignments can drift. Calibration rounds therefore carry both codebooks and compressed weight indices. On upstream calibration rounds, the server reconstructs client models and applies FedAvg.
What this adds
01
Codebook exchange: omit repeated weight-index transmission in ordinary upstream and downstream rounds.
02
Nearest-center updates: reuse stored model structure when receiving codebooks.
03
Periodic calibration: restore weight assignments by occasionally sending centers plus indices.
Abstract
Federated Learning (FL) is a distributed machine learning paradigm that enables learning models from decentralized local data. While FL offers appealing properties for clients' data privacy, it imposes high communication burdens for exchanging model weights between a server and the clients. Existing approaches rely on model compression techniques, such as pruning and weight clustering to tackle this. However, transmitting the entire set of weight updates at each federated round, even in a compressed format, limits the potential for a substantial reduction in communication volume. We propose FedCode where clients transmit only codebooks, i.e., the cluster centers of updated model weight values. To ensure a smooth learning curve and proper calibration of clusters between the server and the clients, FedCode periodically transfers model weights after multiple rounds of solely communicating codebooks. This results in a significant reduction in communication volume between clients and the server in both directions, without imposing significant computational overhead on the clients or leading to major performance degradation of the models. We evaluate the effectiveness of FedCode using various publicly available datasets with ResNet-20 and MobileNet backbone model architectures. Our evaluations demonstrate a 12.2-fold data transmission reduction on average while maintaining a comparable model performance with an average accuracy loss of 1.3% compared to FedAvg. Further validation of FedCode performance under non-IID data distributions showcased an average accuracy loss of 2.0% compared to FedAvg while achieving approximately a 12.7-fold data transmission reduction.
Abstract and overview follow the public preprint; the citation identifies the published version.
With P weights, K centers and b bits per center, ordinary clustering still sends one index per weight. FedCode targets that repeated index cost.
Equation 3, PDF page 2. b abbreviates the source’s wordlength; this is a representation-size expression.
02
Exchange centers in ordinary rounds
Download a sorted codebook; map each local weight to its nearest center; train locally. One K-means run over the entire local model then produces the upload codebook.
Section 4.1 and Algorithm 2, PDF pages 5–6. Downstream mapping is O(P log K); K-means is O(PKI), with I iterations. These are complexity claims, not device timings.
03
Aggregate codebooks by remapping
Concatenate received client codebooks and map each existing global weight to its nearest received center. This operation changes the ordinary server update; it does not average complete client tensors.
Section 4.1 and Algorithm 1, PDF page 5. Global weights are clustered again to prepare the next downlink.
04
Calibrate each direction periodically
Send centers plus indices to reconstruct the sender’s clustered model. The server uses FedAvg after upstream reconstruction. Calibration frequency controls communication and accuracy together.
Section 4.2, PDF page 5. The v1 preprint assigns F1/F2 to directions inconsistently, so the result panel retains those source labels without relabeling them.
Original paper figures & sourcesEnlargeMost FedCode rounds communicate cluster centers upstream and downstream. Periodic transfers of compressed weights recalibrate the client and server models. Figure 2 in the public preprint Evaluation
FedCode reports 14.6× joint reduction at 58.07% accuracy. FedZip’s 19.8× upload reduction becomes 1.9× when the download cost is included.
Joint traffic reduction (×)
Higher is better
015
FedAvg
— Not reported or not applicable in the source table
FedAvg + weight clustering
5.3
FedZip
1.9
FedCode
14.6
Accuracy (%)
Higher is better
0100
FedAvg
61.22
FedAvg + weight clustering
58.78
FedZip
57.98
FedCode
58.07
Experiment details
CIFAR-100, ResNet-20, 10 clients, full participation, 100 rounds, 4 local epochs. FedCode uses 64 centers and calibration rates 0.2/0.5. Accuracy (%) and data transmission reduction (DTR, × FedAvg) are higher-is-better; no uncertainty reported.
Dashes reproduce unreported entries in the source table, not zero communication. These results use one workload and the paper’s configured baselines; MUCSC was not reproduced.
Bidirectional savings against clustering baselines. CIFAR-100, ResNet-20, 10 clients, full participation, 100 rounds, 4 local epochs. FedCode uses 64 centers and calibration rates 0.2/0.5. Accuracy (%) and data transmission reduction (DTR, × FedAvg) are higher-is-better; no uncertainty reported.
Less frequent calibration saves traffic but can sharply reduce accuracy: 264.7× reduction costs 46.88 percentage points in the codebook-only setting.
Joint traffic reduction (×)
Higher is better
0265
1 / 1
5.3
0.5 / 0.5
10.4
0.2 / 0.5
14.6
0.33 / 0.33
15.2
0.1 / 0.1
44.3
0 / 0
264.7
Accuracy change (pp)
-470
1 / 1
-0.86
0.5 / 0.5
-3.46
0.2 / 0.5
-3.15
0.33 / 0.33
-5.94
0.1 / 0.1
-21.64
0 / 0
-46.88
Experiment details
CIFAR-100, ResNet-20, 64 centers, 10 clients, full participation, 100 rounds, 4 local epochs. F1/F2 are the source table’s calibration-rate labels. Accuracy change is in percentage points versus FedAvg; data volume is reported in MB.
No uncertainty is reported. The preprint inconsistently assigns F1/F2 to upstream and downstream in different sections, so the original labels are retained without relabeling their direction.
Calibration controls the accuracy cost. CIFAR-100, ResNet-20, 64 centers, 10 clients, full participation, 100 rounds, 4 local epochs. F1/F2 are the source table’s calibration-rate labels. Accuracy change is in percentage points versus FedAvg; data volume is reported in MB.
With 10% participation, all four selected comparisons show larger accuracy losses under non-IID data. Training budgets and some cluster counts also differ.
Accuracy change (pp)
IID accuracy Δ (pp)Non-IID accuracy Δ (pp)
-40
ResNet-20 / CIFAR-10
-1.51
-1.67
ResNet-20 / CIFAR-100
-3.04
-3.74
MobileNet / CIFAR-10
-0.33
-0.81
MobileNet / CIFAR-100
-1.93
-2.91
Experiment details
10 clients, 10% participation; IID Dir(10) versus non-IID Dir(0.1), with label and quantity skew. Accuracy changes are percentage points versus each FedAvg baseline; joint DTR is a multiplicative reduction. No uncertainty reported.
Appendix B uses longer runs for non-IID data and partial participation; MobileNet also uses more clusters for non-IID data. These rows are not controlled one-variable comparisons.
Partial participation under heterogeneous data. 10 clients, 10% participation; IID Dir(10) versus non-IID Dir(0.1), with label and quantity skew. Accuracy changes are percentage points versus each FedAvg baseline; joint DTR is a multiplicative reduction. No uncertainty reported.
Results use the November 2023 arXiv v1 preprint, separately from the IEEE EDGE 2024 publication.
Ten-client simulations; budgets vary across settings and tables report no uncertainty.
Data and models
CIFAR-10/100 with ResNet-20 and MobileNet v2; 12-class SpeechCommands v2 with YAMNet.
Federated setting
10 clients; 10% or 100% participation; Dirichlet concentrations 10 and 0.1; Adam, four local epochs, batch size 128.
Compared with
FedAvg, FedAvg with weight clustering, and FedZip; MUCSC could not be reproduced from its reported clustering details.
Measured scope
Test accuracy, communication volume/DTR, and bits per parameter; computational complexity is analyzed, without a measured edge-device energy or latency benchmark.
Scope & limitations
This page uses the November 2023 arXiv v1 preprint, whose summary statistics differ from the IEEE EDGE 2024 published version. Results from those versions are not combined.
Codebook size, calibration frequency, participation, and training duration jointly affect the results. Savings from a selected setting are not a universal compression guarantee.
Reported tables contain no run-to-run uncertainty. Model- and distribution-specific settings differ, including up to 2,000 rounds in the MobileNet appendix.
FedCode is a communication method. Keeping raw data local and compressing updates do not provide a demonstrated privacy guarantee against inference or malicious clients.