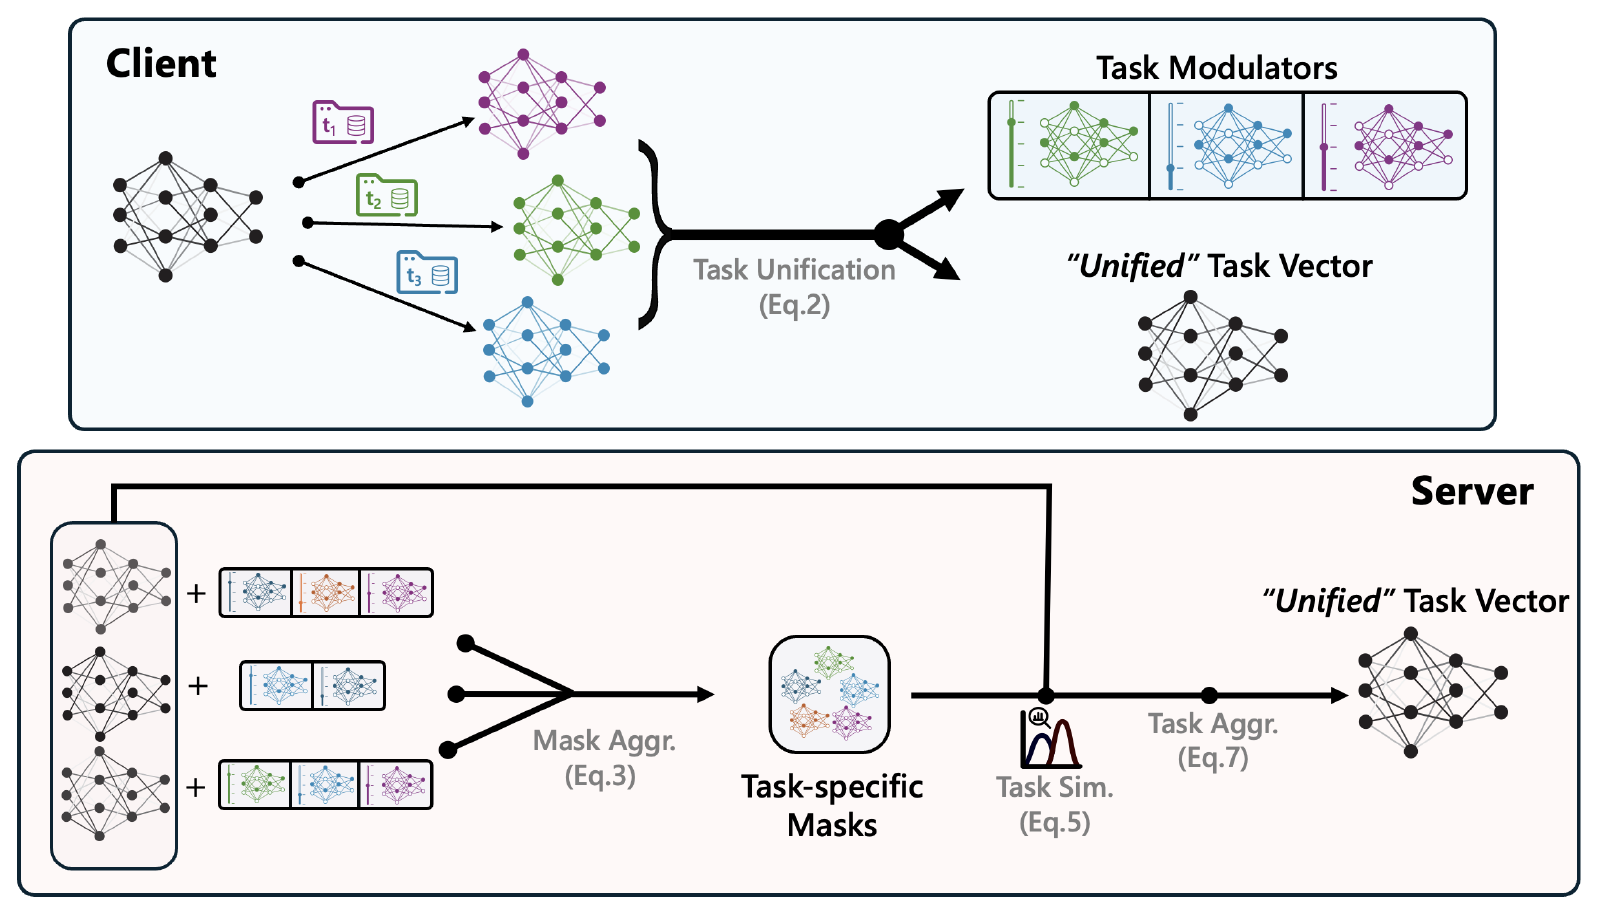
Clients with several tasks produce updates that can interfere. MaTU sends one unified task vector plus per-task masks and scalars, preserving task differences while enabling server aggregation within tasks and transfer between related tasks.
Shared updates · Task-specific models
Client 1Tasks A + B
Client 2Tasks A + C
Local tasks
→
Shared serverTask vectors
CLIENT 1 · LOCAL TRAINING
Two tasks · one origin
Pretrained θpOne shared origin
Task A
τA= θA − θp
+2−1+4+1
Task B
τB= θB − θp
+1−3−2+2
Train each taskKeep a common coordinate system
Separate local training · Task vector = fine-tuned − pretrained
Client 1Tasks A + B
Client 2Tasks A + C
Unify
→
Shared serverTask vectors
CLIENT 1 · TASK UNIFICATION
Elect direction · retain magnitude
Task A
+2−1+4+1
Task B
+1−3−2+2
Sum
+3−4+2+3
Elect sign
+−++
Unified τ
+2−3+4+2
Sign of sumLargest aligned magnitude
Sign of summed updates · Largest magnitude aligned with that sign
Updated vector + modulators → task-specific weights → next local round
1 / 6
What this adds
01
Compact task representation: elect a shared vector and retain lightweight task-specific modulators.
02
Selective transfer: combine same-task updates with sign-aligned related tasks.
03
No retained client weights: the server computes task-level updates without storing client-specific models across rounds.
Abstract
Federated Learning (FL) traditionally assumes homogeneous client tasks; however, in real-world scenarios, clients often specialize in diverse tasks, introducing task heterogeneity. To address this challenge, Many-Task FL (MaT-FL) has emerged, enabling clients to collaborate effectively despite task diversity. Existing MaT-FL approaches rely on client grouping or personalized layers, requiring the server to manage individual models and failing to account for clients handling multiple tasks. We propose MaTU, a MaT-FL approach that enables joint learning of task vectors across clients, eliminating the need for clustering or client-specific weight storage at the server. MaTU constructs a single “unified” task vector per client and leverages lightweight task-specific modulators — binary masks and scalar rescalers — to disentangle and adapt per-task behavior. This design ensures stateless server aggregation and naturally scales to large task sets with minimal communication overhead. Evaluated across 30 datasets, MaTU achieves superior performance over state-of-the-art MaT-FL approaches, with results comparable to per-task fine-tuning, while delivering significant communication savings.
Each client fine-tunes its assigned tasks separately. A task vector is the change from the common pretrained weights. The experiments use ViT-B/32 with rank-16 LoRA on vision classification tasks.
Section 3.1 · p. 2. θt* denotes fine-tuned task weights and θp the shared pretrained origin.
02
Elect the unified vector
At each coordinate, take the sign of the sum of local task vectors. Among entries agreeing with that sign, retain the largest magnitude. This election preserves a common direction without averaging away its amplitude.
Equation (2) · p. 3. σ is the elected sign, μ the largest aligned magnitude; ⊙ denotes elementwise multiplication.
03
Retain task-specific modulation
Each task keeps a binary mask for entries aligned with its own signs and a scalar matching its original total absolute magnitude. These modulators produce approximate task updates from the unified vector.
Section 3.2, “Forming clients updates” · p. 4. Client and round indices are omitted consistently; mt is a task mask and λt its scalar.
04
Aggregate and return updates
The server uses task agreement masks to combine same-task clients, then transfers sign-aligned updates from up to κ related tasks with similarity above 0.5. It reunifies the updated vectors for each client and returns new masks and scalars for the next local-training round.
Equations (3)–(7) · p. 4. “Stateless” means no client-specific weights retained across rounds; task-level aggregation still occurs. Cross-task transfer is not uniformly beneficial in the ablations.
Original paper figures & sourcesEnlargeClients communicate one unified vector plus a binary mask and scalar for each task. The server combines same-task updates and transfers information between tasks whose update directions agree. Figure 1 in the public preprint Evaluation
One task per client. Eight vision tasks, ImageNet-21k-pretrained ViT-B/32 with rank-16 LoRA, 30 clients, 20% participation, one local epoch. Mean task accuracy (%), higher is better; reported bitrate in millions of bits per task per round, lower is better.