A new voice command should need examples, not a new training run. PLiX learns an acoustic embedding across languages, then recognizes unseen words by comparing a query with prototypes built from a few labeled support clips.
Learn once · Recognize new words
TrainingMultilingual episodesLearn a space
01 / 05
Learn an acoustic space
Word episode
Go
Stop
QueryGo
Both
Audio encoderLearn embeddings
Compare + learn
Support means
Go
Stop
Query distances
Cross-entropyKnown query label: Go
Query loss→Update encoder→New episode
Multilingual training · Changing word episodes
RecognitionSame frozen encoderNew vocabulary
02 / 05
New words → embeddings
Labeled supports
Go
Stop
Encode
Audio encoderFixed weights
Word embeddings
Go
Stop
Support clips→Reference words
Labeled supports · Shared encoder · Fixed weights
RecognitionSame frozen encoderNew vocabulary
03 / 05
Supports → word prototypes
Same embedding space
One mean per word
Go
Stop
Support only
One word · One mean embedding
RecognitionSame frozen encoderNew vocabulary
04 / 05
Query → nearest word
Distance to prototypes
?
Audio encoderFixed weights
Nearest wordGo
Separate query · Squared Euclidean distance
RecognitionSame frozen encoderNew vocabulary
05 / 05
New vocabulary · Same encoder
New supports
Left
Right
Encode
Audio encoderFixed weights
Average
New prototypes
Left
Right
Fixed encoder+Replace prototypes
New supports → New prototypes · No retraining
1 / 5
What this adds
01
Multilingual episodic training learns to compare words across 20 languages.
02
Support-derived prototypes let a frozen encoder recognize a new vocabulary without retraining.
03
Transfer and hardware evaluation examine unseen languages, language identification and encoder latency/energy.
Abstract
As technology advances and digital devices become prevalent, seamless human-machine communication is increasingly gaining significance. The growing adoption of mobile, wearable, and other Internet of Things (IoT) devices has changed how we interact with these smart devices, making accurate spoken words recognition a crucial component for effective interaction. However, building robust spoken words detection system that can handle novel keywords remains challenging, especially for low-resource languages with limited training data. Here, we propose PLiX, a multilingual and plug-and-play keyword spotting system that leverages few-shot learning to harness massive real-world data and enable the recognition of unseen spoken words at test-time. Our few-shot deep models are learned with millions of one-second audio clips across 20 languages, achieving state-of-the-art performance while being highly efficient. Extensive evaluations show that PLiX can generalize to novel spoken words given as few as just one support example and performs well on unseen languages out of the box. We release models and inference code to serve as a foundation for future research and voice-enabled user interface development for emerging devices.
The multilingual base uses EfficientNet-v2 Medium, trained in 10-way, 5-shot episodes across 20 languages. Training and test vocabularies contain disjoint words.
§2.2–3.3. The TinyNet-E alternatives are separately trained language-specific models, not a compressed copy of the multilingual base.
02
Average support embeddings only
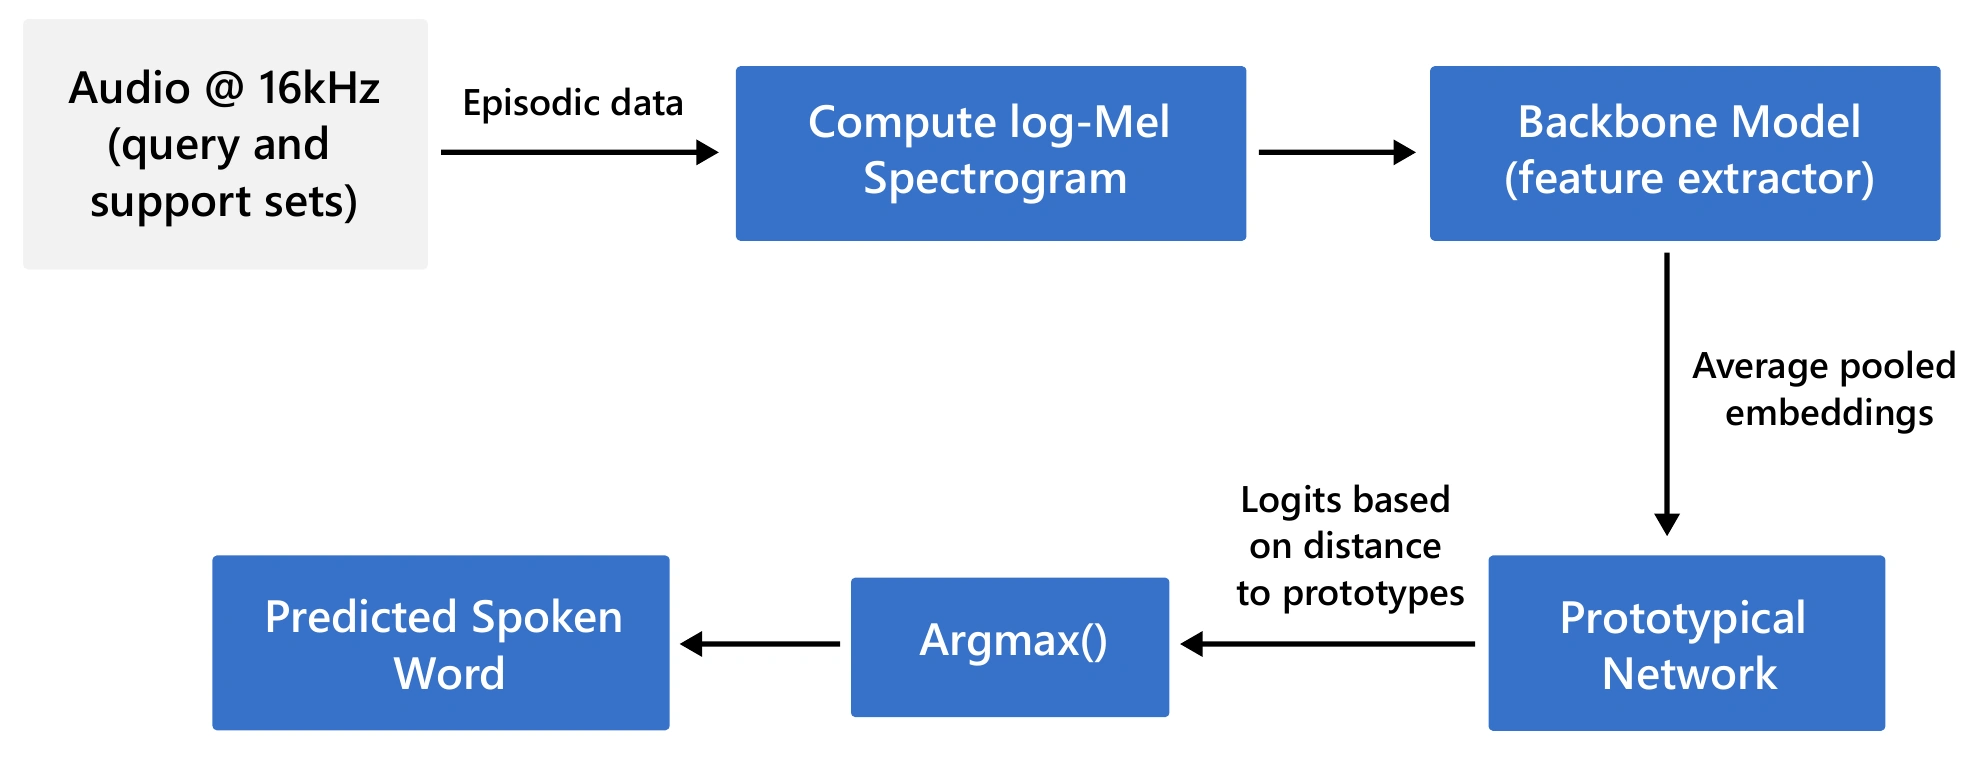
For a requested word c, encode each labeled support clip and average its embedding. The query is excluded from this computation.
§2.1.2, p. 3; Figure 1 explicitly separates the query path from mean pooling.
03
Classify without a weight update
Choose the prototype closest to the query embedding in squared Euclidean distance. Changing support clips changes the classifier while leaving encoder weights fixed.
§2.1.2, expressed equivalently to the paper’s argmax of negative squared distance. Most word tests use one-second clips.
04
Separate recognition from encoder cost
Recognition tests vary vocabulary size, support count and language. Hardware profiling measures encoder inference only on Raspberry Pi 4, Jetson Nano and Pixel 7.
Table 1 excludes log-mel extraction and prototype computation. Released weights and inference instructions are linked through aaqibsaeed/plixkws on Hugging Face.
Original paper figures & sourcesEnlargeA shared acoustic encoder maps support examples and incoming speech into the same space. Distances to the support-set prototypes determine which word was spoken. Figure 2 · public preprint, p. 4 Evaluation
Results
Quantized encoder latency
Encoder only · 200 inference runs · excludes preprocessing and prototype classification
Latency (ms) ↓ Lower is better
Small · TinyNet-EBase · EfficientNet-v2 M
060120
Pixel 7 · quantized
Small · TinyNet-E: 5.12
Base · EfficientNet-v2 M: 78.07
Raspberry Pi 4 · quantized
Small · TinyNet-E: 6.92
Base · EfficientNet-v2 M: 107.13
Jetson Nano · quantized
Small · TinyNet-E: 7.32
Base · EfficientNet-v2 M: 101.37
Quantized encoder energy
Encoder energy · 200 inference runs · external power monitor
Encoder energy. Same encoders and device configurations as the latency panel; average over 200 inference runs measured with an external power monitor. Energy in millijoules, lower is better; no dispersion reported.
 HF