An emotion model can fit one speech corpus and fail on another. DA-MLDG rehearses source-domain shifts during training and weights them with an energy-gap estimate. The study finds mixed generalization gains and exposes limits of the representations and benchmarks.
Domain-shift-aware meta-learning weights the loss on a held-out source subset using an energy gap.
02
Seven cross-corpus scenarios make both improvements and failure cases visible.
03
Representation analysis compares log-mel inputs with TRILLsson embeddings without claiming domain shift is solved.
Abstract
Speech Emotion Recognition (SER) refers to the recognition of human emotions from natural speech, vital for building human-centered context-aware intelligent systems. Here, domain shift, where models’ trained on one domain exhibit performance degradation when exposed to an unseen domain with different statistics, is a major limiting factor in SER applicability, as models have a strong dependence on speakers and languages characteristics used during training. Meta-Learning for Domain Generalization (MLDG) has shown great success in improving models’ generalization capacity and alleviate the domain shift problem in the vision domain; yet, its’ efficacy on SER remains largely unexplored. In this work, we propose a “domain-shift aware” MLDG approach to learn generalizable models across multiple domains in SER. Based on our extensive evaluation, we identify a number of pitfalls that contribute to poor models’ DG ability, and demonstrate that log-mel spectrograms representations lack distinct features required for MLDG in SER. We further explore the use of appropriate features to achieve DG in SER as to provide insides to future research directions for DG in SER.
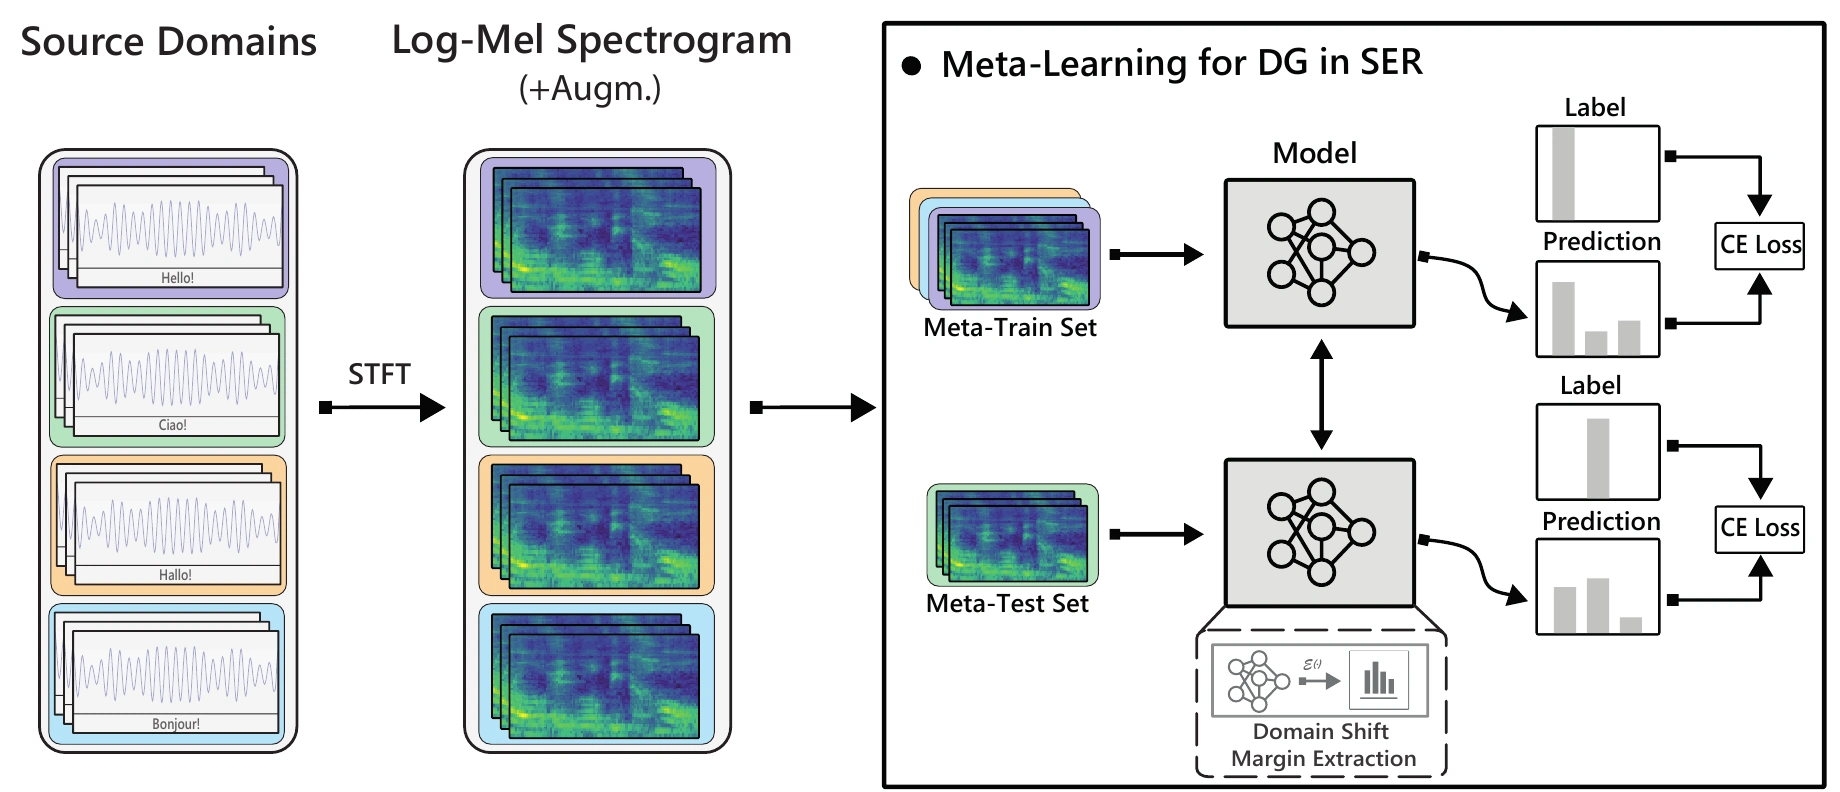
Partition source domains into disjoint sets S′ and V at each iteration. A gradient step on S′ produces adapted parameters θ′.
§III, Eq. 2 and Algorithm 1. V is a source meta-test subset, not the final target test corpus.
02
Use energy as a shift proxy
Compute each subset’s average log-sum-exp of logits with θ′ and temperature 1. The absolute gap supplies γ, the adaptive weight.
Eq. 3, printed p. 423. The score is proposed as a proxy for domain shift, not a measured distance between speech distributions.
03
Optimize the weighted outer objective
Minimize source training loss plus γ times meta-test loss after adaptation. The outer optimization accounts for how θ′ depends on θ.
Eq. 2. The formula presents the stated objective rather than Algorithm 1’s outer-update line, which omits an explicit gradient symbol.
04
Evaluate representation and transfer together
Compare ResNet-18 with log-mel inputs against a variant using TRILLsson embeddings. Seven source/target scenarios cover same-language and cross-language transfer.
Tables I, III and IV; ten trials per setting. The target corpora remain unseen during training.
Original paper figures & sourcesEnlargeTraining repeatedly simulates a domain shift between source datasets. The estimated shift controls the influence of the meta-test loss when updating the shared emotion model. Figure 1 · PerFail paper, p. 423 Evaluation
Results
Cross-corpus emotion recognition
Log-mel inputs · seven scenarios · mean accuracy over ten trials
Generalization gains are uneven. Five-emotion SER with VoxCeleb-pretrained ResNet-18 and log-mel inputs; source and target corpora are defined in Table I. Mean target accuracy (%) over ten trials; higher is better. No dispersion is reported for these results.
Scenario · target
Deep-All (%)
RSC (%)
MLDG (%)
DA-MLDG (%)
1 · IEMOCAP
26.95
32.36
27.61
31.35
2 · RAVDESS
43.40
44.78
38.86
39.41
3 · TESS
47.03
43.77
46.29
46.80
4 · CaFE
43.16
39.97
42.57
43.21
5 · AESDD
60.65
56.69
60.45
62.26
6 · ShEMO
31.54
40.70
37.87
38.79
7 · ShEMO
40.19
40.27
34.51
37.11
With pretrained speech embeddings
TRILLsson inputs · same seven scenarios · mean accuracy over ten trials
@inproceedings{gandhi2023damldg,
  author = {Gandhi, Raeshak King and Tsouvalas, Vasileios and Meratnia, Nirvana},
  title = {On efficacy of Meta-Learning for Domain Generalization in Speech Emotion Recognition},
  booktitle = {2023 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops)},
  year = {2023},
  pages = {421--426},
  note = {PerFail 2023: Second International Workshop on Negative Results in Pervasive Computing},
  doi = {10.1109/PerComWorkshops56833.2023.10150265},
  url = {https://doi.org/10.1109/PerComWorkshops56833.2023.10150265}
}