Learn task and compression together
Each client minimizes cross-entropy plus a weight-clustering penalty. The local warm-up uses β=0 before enabling clustering with β=1.
Equation 1, PDF page 3. μ denotes learnable centroids; C is their count.
Compress both directions of federated training.
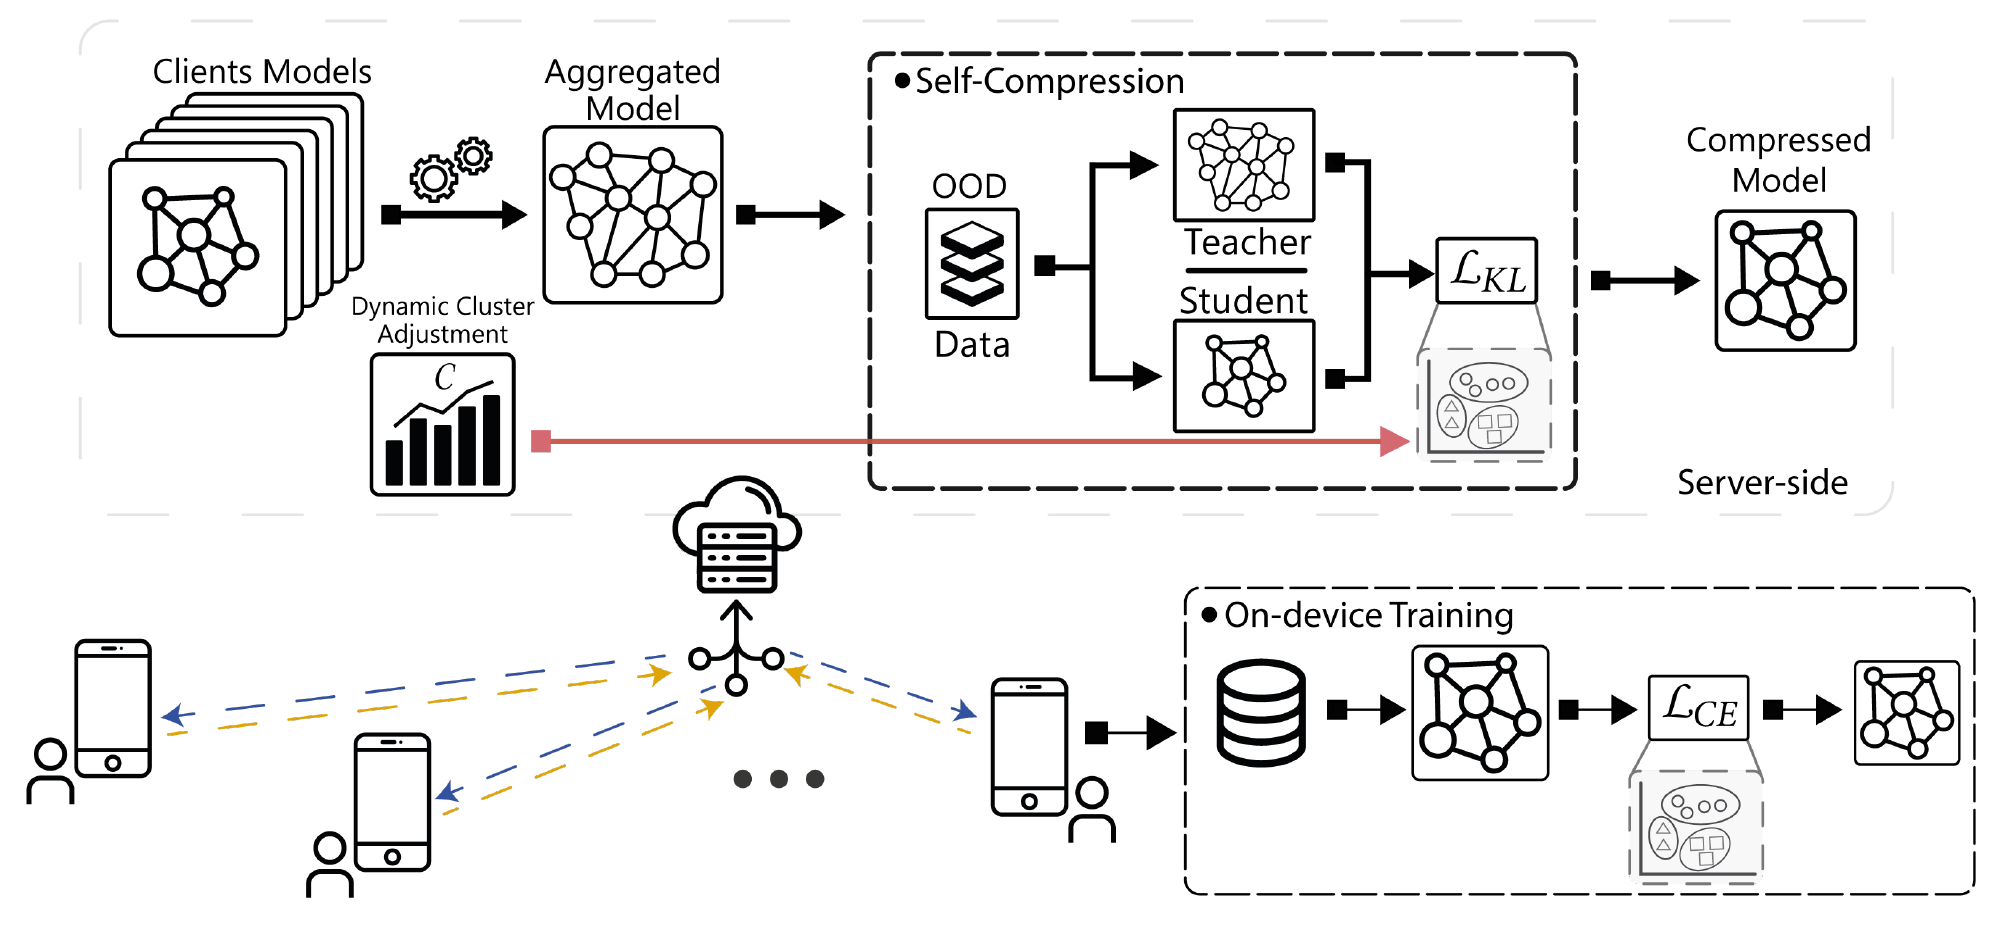
Compress both directions of federated training. Clustering makes client uploads compact, but averaging can undo that structure. FedCompress restores it with server-side distillation and adjusts cluster capacity using an unlabeled representation score.
Dual compression: clustered local training plus server self-compression after aggregation.
Adaptive capacity: use embedding effective rank to guide the number of shared weight values.
Vision and audio evidence: report communication, model size and device inference separately.
Federated Learning (FL) is a promising technique for the collaborative training of deep neural networks across multiple devices while preserving data privacy. Despite its potential benefits, FL is hindered by excessive communication costs due to repeated server-client communication during training. To address this challenge, model compression techniques, such as sparsification and weight clustering are applied, which often require modifying the underlying model aggregation schemes or involve cumbersome hyperparameter tuning, with the latter not only adjusts the model's compression rate but also limits model's potential for continuous improvement over growing data. In this paper, we propose FedCompress, a novel approach that combines dynamic weight clustering and server-side knowledge distillation to reduce communication costs while learning highly generalizable models. Through a comprehensive evaluation on diverse public datasets, we demonstrate the efficacy of our approach compared to baselines in terms of communication costs and inference speed.
Read more ↗Each client minimizes cross-entropy plus a weight-clustering penalty. The local warm-up uses β=0 before enabling clustering with β=1.
Equation 1, PDF page 3. μ denotes learnable centroids; C is their count.
Keep the underlying aggregation rule. Then optimize a clustered student to match the temperature-scaled teacher outputs on unlabeled auxiliary data held by the server.
Equation 2, PDF page 4, with model arguments abbreviated. The KL term includes the paper’s temperature scaling.
Normalize the singular values of local embeddings and compute their effective rank. This is an unlabeled proxy for representation quality, not a generalization guarantee.
Dynamic weight-clustering section, PDF page 4. r is the normalized singular-value spectrum; the implementation description adds a small stability constant.
Start with a small cluster count and increase it when score progress stalls. The prose uses a three-round window and patience, with an optional maximum cluster budget.
PDF page 4. This describes the intended schedule; Appendix A contains notation differences and is not an independently verified implementation.
CIFAR-100 · ResNet-20 · 20 clients · 20 rounds · reduction relative to FedAvg
20 clients · 20 rounds · accuracy mean of 2 trials
| Dataset | FedCompress Δ accuracy (pp) | Communication reduction (×) |
|---|---|---|
| CIFAR-10 | −1.83 | 4.53 |
| CIFAR-100 | −1.88 | 3.80 |
| PathMNIST | −1.72 | 4.79 |
| SpeechCommands | −0.42 | 5.04 |
| VoxForge | −0.31 | 5.41 |
@inproceedings{tsouvalas2024fedcompress,
  title = {Communication-Efficient Federated Learning through Adaptive Weight Clustering and Server-Side Distillation},
  author = {Vasileios Tsouvalas and Aaqib Saeed and Tanir Ozcelebi and Nirvana Meratnia},
  booktitle = {ICASSP 2024 - 2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)},
  year = {2024},
  pages = {5805--5809},
  doi = {10.1109/ICASSP48485.2024.10447174},
  url = {https://arxiv.org/abs/2401.14211},
  eprint = {2401.14211},
  archivePrefix = {arXiv}
}